Instructor’s check
What evidence justified relying on the AI here, and what would have changed the call?
Change one condition, like details AI tends to miss, and ask again.
How this figure works
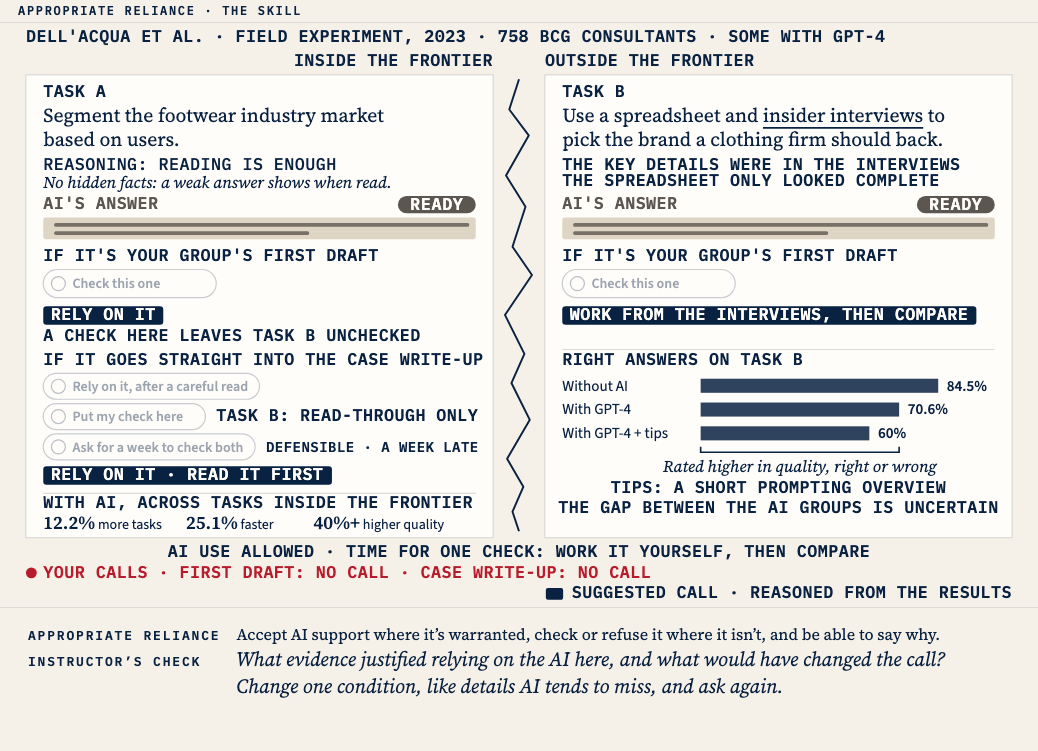
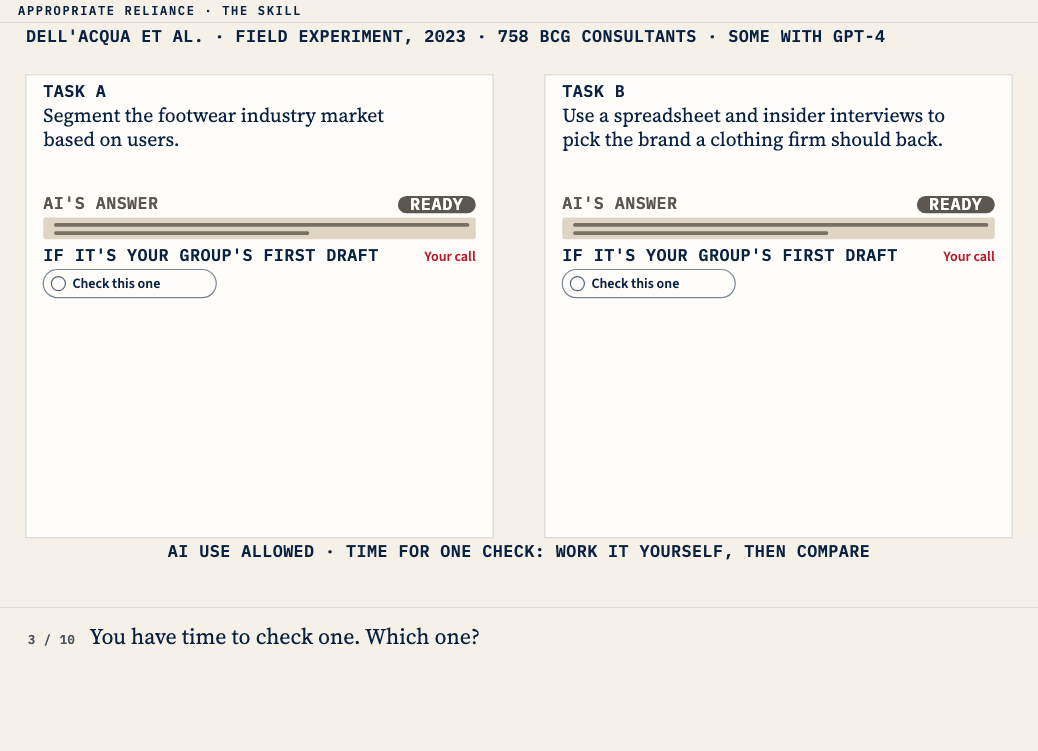
Appropriate reliance means accepting AI support where it's warranted, checking or refusing it where it isn't, and being able to say why. Checking takes time, so the figure gives you two consulting tasks from a 2023 field experiment as a team project for a class where AI use is allowed, and time to check only one. You decide where the check goes before you see what happened, then make one more call after a condition changes. You can skip either question, and Start over plays the whole figure from the beginning. Illustration based on Dell'Acqua et al. (2023), a study of consultants: the tasks and results are the study's, and the class project, the time budget, the first draft and the case write-up are this figure's.
PME means professional military education. Its example comes from The Irreducible Officer, the National War College essay.
After you make your call: make or skip both calls to open this.
After you make your call: what a good answer says, the evidence, the tasks
What a good answer says
A good answer says where the check went and why. This is the figure's reasoning from the study's results; the study itself didn't test checking, a time budget, or what the work was for. Task B's deciding details were in the interviews, and the spreadsheet only looked complete. Graders rated the AI users' recommendations higher whether or not they were right, so a read-through wouldn't show a miss. That's where the one check belongs, and it starts from the interviews. Task A is the kind of work the study found inside the frontier, and the figure reads it as having no hidden facts: a weak segmentation shows when read. That covers quality, with one known blind spot: the study also found AI users' ideas less varied, and a careful read of one segmentation won't show that. As a first draft it can go without a check. When the segmentation goes straight into the case write-up, it is still inside the frontier, so the call is still to rely on it, but now someone has to read it carefully first. What would move the check is a detail the AI tends to miss: if the segmentation turned on something buried in the source material, as Task B's answer did, Task A would need working through too. Moving the one check would leave Task B, the risky task, to a read-through; asking for a week to check both is defensible, and it misses the deadline by a week. Changing one condition and asking again shows whether the student has a reason for the call.
Evidence
Dell'Acqua et al., Navigating the Jagged Technological Frontier, HBS working paper 24-013 (2023). In the field experiment, 758 BCG consultants, about 7% of the firm's individual-contributor consultants, were split between two sets of tasks: 385 worked the tasks inside the frontier and 373 the task outside it. Within each set they were randomly assigned to work without AI, with GPT-4, or with GPT-4 plus a prompt-engineering overview. On the tasks inside the frontier, consultants with AI finished 12.2% more tasks, 25.1% faster and at more than 40% higher quality. There was a cost in variety: on the first inside task, ideas for a new shoe, AI users' ideas were better but showed "a marked reduction in the variability of these ideas compared to those not using AI" (p. 12). On the task chosen to fall outside it, consultants without AI were right about 84.5% of the time, with GPT-4 70.6%, and with GPT-4 plus the overview 60%: in the working paper's words, with the two AI groups pooled, "19 percentage points less likely to produce correct solutions" (abstract). Graders still rated the AI users' recommendations higher in quality "regardless of the correctness of their answer" (p. 15). Two limits: the gap between the two AI groups is significant only at the 10% level, and so is the higher rating among wrong answers alone. The study examined GPT-4 as it was in 2023.
About the tasks
The tasks inside the frontier were 18 product-development questions for a fictional footwear company. Consultants generated ideas for a new shoe, segmented the market by users, listed the steps to launch it, and wrote a press release and a persuasive memo. On the task built to fall outside the frontier, consultants told a fictional clothing company's CEO which of its brands to invest in, working from a spreadsheet of financial data and interviews with company insiders. The spreadsheet was designed to look complete, but the deciding details were in the interviews, and the authors designed the task so that GPT-4 would get it wrong. In the study each consultant worked one set of tasks; the choice of where to spend one check, and the launch-plan condition, are this figure's. The task wording on screen is paraphrased. The frontier moves as models change; this is where it sat in 2023, with GPT-4.